Notes / Chertma
Chertma: type plain ASCII, get correct Uzbek
Uzbekistan is moving to a new Latin alphabet that no phone keyboard has. Chertma restores ş ç ö ğ from plain typing, offline, using a 4.9-million-word lexicon, and refuses to touch anything it is not sure about.
- Engine size
- 12 KB gzipped
- Word forms in the lexicon
- 4,892,125
- Precision, Latin input
- 99.9%
- Network requests after load
- 0
- Bot
- @Chertmabot
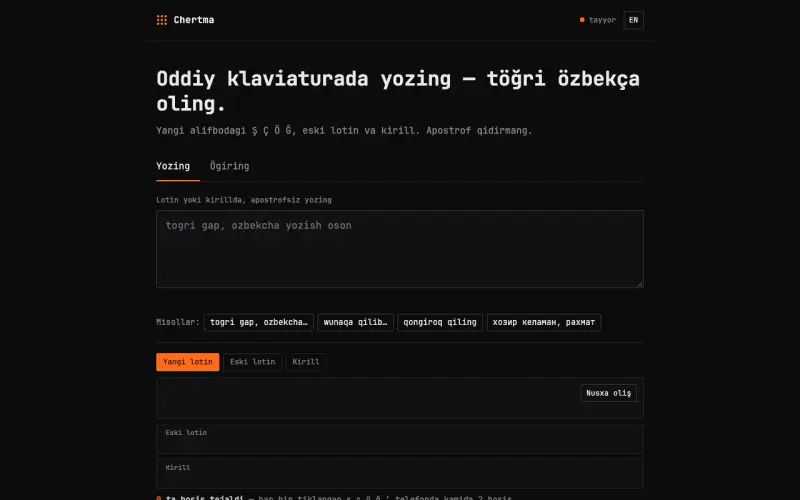
Uzbekistan is moving its Latin alphabet from sh ch oʻ gʻ to ş ç ö ğ. For years people will write in three scripts at once: the old Latin, the new Latin and Cyrillic. No phone keyboard has the new letters, so people skip the marks, search breaks, and every text ends up a little wrong.
Chertma fixes that from the keyboard you already have. You type togri gap, ozbekcha yozish oson and get töğri gap, özbekça yoziş oson in the new Latin, toʻgʻri gap, oʻzbekcha yozish oson in the old one, or the same sentence in Cyrillic. It also understands Uzbek typed on a Russian layout: хозир келаман, рахмат comes back as hozir kelaman, rahmat.
The one rule
Chertma restores what a keyboard destroyed, and nothing else.
A correction is allowed only when the typed word and the corrected word have the same skeleton: the word with every distinction a keyboard could lose folded away. ş, sh, s and w all fold to one class; so do ö, oʻ and o; so do ğ, gʻ, gh and g; apostrophes disappear; Cyrillic is transliterated first. So тўғри, toʻgʻri, togri and töğri all share the skeleton tOGri. If no real word shares the skeleton of what you typed, your input comes back byte for byte.
That rule is why Chertma does not touch dialect or style. kelaslar, qisela and balu stay exactly as you wrote them. It corrects spelling, not the way you speak.
A missed correction is a small loss. A wrong one is the failure Chertma exists to avoid.
Measured, not promised
The engine is plain JavaScript modules with zero dependencies, no access to the page and no network access.
| Budget | Measured | |
|---|---|---|
| Engine, gzipped | 30 KB | 12.0 KB |
| Small lexicon (50,000 words, 200,000 pairs), gzipped | 2 MB | 0.74 MB |
| Full lexicon (400,000 words, 2,000,000 pairs), gzipped | 8 MB | 7.34 MB |
| Loading the small lexicon | 400 ms | 24 ms |
| A suggestion, 95th percentile | 5 ms | 0.8 ms |
Quality is measured on an unfiltered sample of real text. On Latin text with the apostrophes removed it made 695 corrections with 1 wrong (99.9% precision) and missed 290. On Cyrillic typed on a Russian layout it made 471 corrections, 14 wrong (97.1%), and missed 686. It misses on purpose rather than guess.
The known limits are written down. A word that is already a real word is never rewritten, so in sosib pisib togri the word pisib stays, because it is a real word ("sneaking up"), even though the idiom is şoşib pişib. Words the lexicon does not know stay exactly as typed.
The lexicon underneath
The skeleton index is the real product; the converter and the Telegram bot are only doors to it. I built it from 1.75 billion word tokens of open Uzbek text: 1.43 billion from books, 296 million from news and 25.5 million from Telegram channels, taken from the tahrirchi/uz-books-v2 and tahrirchi/uz-crawl datasets.
The result is 4,892,125 word forms with their frequencies, 23,160,605 word pairs and a skeleton index that groups the words a keyboard makes indistinguishable. I published all of it on Hugging Face as uz-lexicon-skeleton under CC BY 4.0, so anyone building an Uzbek keyboard, spell checker or transliteration model can use it. The details are in the note on open data.
Private by design
Your text never leaves your device. Once the page and the lexicon are loaded, no request goes to the network: no cookies, no analytics. After the first visit it works offline, on a plane or with the mobile data switched off. The site even counts the taps you saved, because every restored ş ç ö ğ ʼ is at least two taps on a phone keyboard.
If you live in Telegram, @Chertmabot does the same job in a chat.
What is next
An open benchmark for the new alphabet, uz-alphabet-bench, is being checked by hand and will be published when it is ready. Until then: open chertma.maqsudjon.com, type the way you always type, and copy out correct Uzbek.